nemotron-halloween
MonsterHouse is a DIY Halloween interactive garage‑door character built on NVIDIA Nemotron models that listens, talks, and animates in real time on a single workstation.
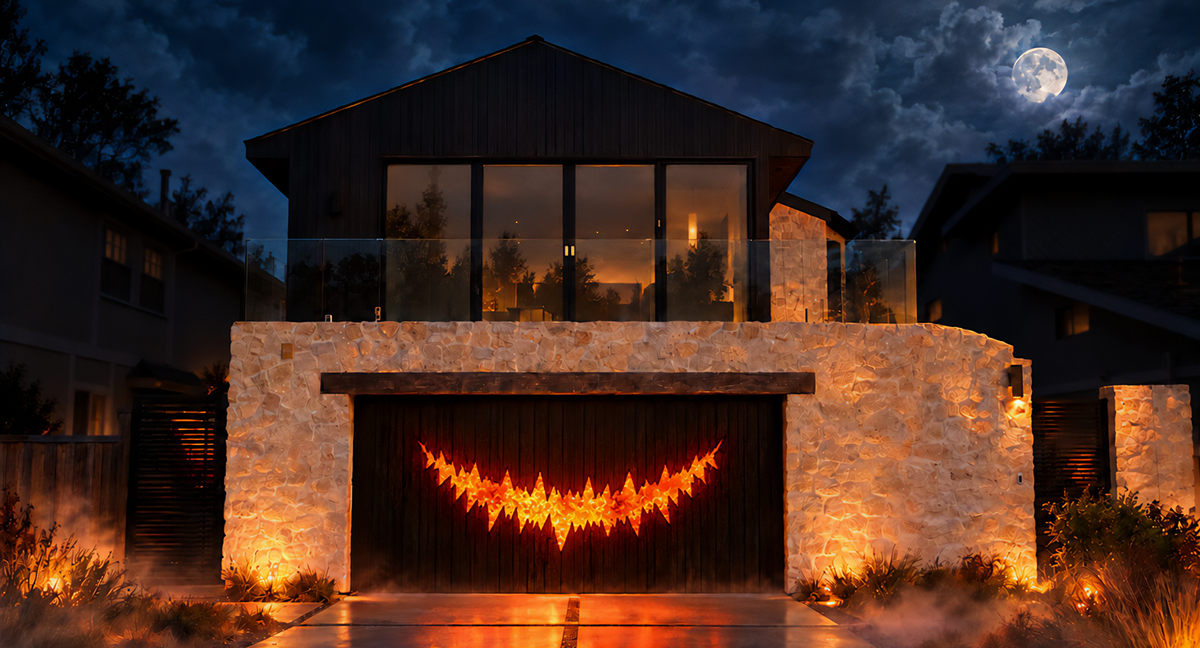
MonsterHouse: A Grumpy Halloween Companion
TL;DR: MonsterHouse is an interactive projection I created for Halloween. He listens to trick‑or‑treaters, answers in the voice of a grumpy old pirate ship and softens when visitors remember their manners. He is built on the NVIDIA Nemotron Voice Agent with Nemotron ASR, Nemotron 3.5 Bolt E4B 4GB, Magpie TTS Zeroshot and Audio2Face‑3D, and runs on a single workstation.
---
1. How the System Works
The pipeline consists of four tightly coupled stages, each powered by an NVIDIA model:
- Listening – Nemotron 3 ASR (streaming speech‑to‑text) converts a child’s spoken “trick‑or‑treat” into text.
- Thinking – Nemotron 3.5 Bolt E4B 4GB (a small, locally‑run LLM) generates a reply. A LoRA adapter injects the grumpy‑pirate personality and tracks conversation state (greeting → complaint → softening).
- Speaking – Magpie TTS Zeroshot takes the generated text and a short reference recording of my own pirate‑style voice, producing a synthetic voice that matches the desired mood (grumpy, amused, etc.).
- Animating – Audio2Face‑3D receives the clean speech waveform and drives a custom Unreal Engine 5 facial rig, making the wooden garage‑door mouth move in sync with the audio.
A lightweight control daemon – the Nemotron Voice Agent – orchestrates these components, handling buffering, latency compensation (≈100 ms), and error recovery. All of this runs on two Blackwell GPUs: an RTX PRO 6000 for the language and voice models, and an RTX PRO 4000 for Unreal rendering.
---
2. Building the Grumpy Character
The Visuals
The mouth rig was the first piece. I modeled a split‑board “jaw” in Autodesk Maya, exported it as a skeletal mesh, and imported it into Unreal. Simple fire particles and a faint glow give the impression of a haunted, creaking structure without needing eyes or eyebrows.
The Personality
The backstory – a sunken pirate ship reborn as a garage door – informs the dialogue flow. The LoRA was trained on a 5 000‑turn dataset of pirate‑flavored exchanges, teaching the model to:
- Reject visitors initially (e.g., “I’m busy grumbling, go bother the neighbors!”)
- Yield when a polite “please” is heard
- Offer a warm farewell after a “thank you”
The conversation state is stored locally, so the house remembers each child’s progress and avoids repeating the same grumble.
---
3. Optimising Performance
- Latency – End‑to‑end speech‑to‑audio latency averages 1.7 s for live generation (Bolt Q4 + Magpie) and 0.7 s when using cached responses. Speech‑end detection adds a 300 ms silence buffer.
- Resource Management – The 4‑bit quantised Bolt model fits comfortably in 4 GB VRAM, leaving headroom for the TTS and Audio2Face pipelines.
- Caching – Frequently used greetings and candy jokes are pre‑generated and stored, reducing both compute load and response time.
---
4. The Control Desk
A custom UI sits on top of the Voice Agent, offering:
- Soundboard for triggering cached lines
- Mood selector to switch between grumpy, amused, or delighted tones
- Conversation monitor showing live transcript, model logits, and visitor count (YOLO + ByteTrack)
- Demo mode where the house explains its backstory without needing a visitor
- Microphone mode allowing the operator to speak directly through the house, bypassing ASR and generation
These tools let me fine‑tune the experience on the fly, ensuring the monster never gets stuck in an endless argument.
---
5. Takeaways for Your Own Halloween Project
- Start with a solid voice‑agent foundation – NVIDIA’s Nemotron Voice Agent provides ready‑made orchestration, saving weeks of glue‑code.
- Choose a lightweight LLM – Bolt E4B’s 4‑bit version delivers acceptable conversational quality while staying within a single‑GPU budget.
- Leverage zero‑shot TTS – Magpie’s reference‑sample approach means you can craft a unique voice without training a full TTS model.
- Separate compute loads – Splitting language/voice and graphics across two GPUs keeps frame rates stable even when the dialogue model spikes.
- Cache what you can – Pre‑rendered greetings and jokes dramatically cut latency and make the character feel more responsive.
---
Closing Thoughts
MonsterHouse turned a simple garage door into a memorable Halloween host, blending speech recognition, language generation, text‑to‑speech, and real‑time 3‑D animation into a single, self‑contained workstation. The project showcases how NVIDIA’s Nemotron ecosystem can power interactive characters without relying on cloud services, making it ideal for offline events, exhibitions, or any scenario where low latency and privacy matter. If you have a spare Blackwell GPU and a penchant for spooky storytelling, give it a try – the house is always looking for new visitors (and a polite "please").
Source
Read original sourceWhy we picked this
Core release of a new AI model (nemotron) on Hugging Face