GLM-5.3: How Chinese labs keep stride with the frontier
Z.ai’s GLM‑5.3, a 750B‑parameter model, outperforms many U.S. rivals on coding benchmarks, showing China’s post‑training edge.
Why Now
Z.ai announced GLM‑5.3, released in the coding plan and soon to be open‑weight on Hugging Face, after GLM‑5.2’s success.
What Happened
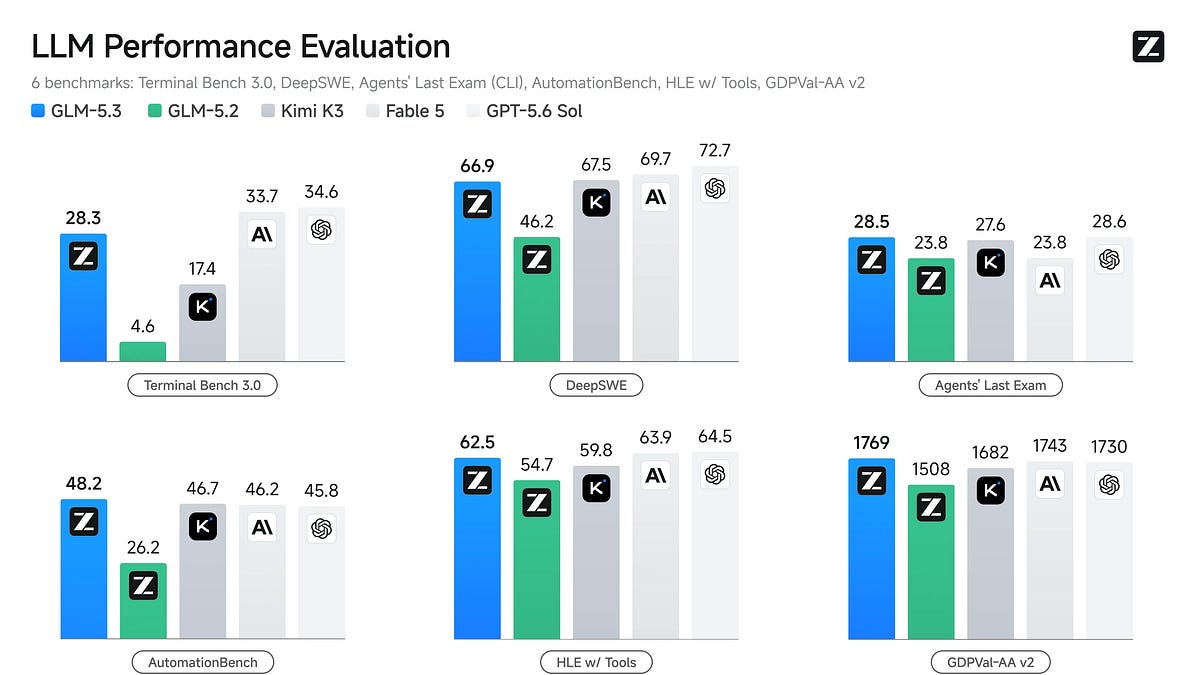
GLM‑5.3 surpasses Moonshot AI’s Kimi K3 on many benchmarks and beats Claude Fable 5 or GPT‑5.6‑Sol on some. It has ~750 B parameters, a third of Kimi K3’s size. Z.ai attributes the gains to extensive post‑training with more environments, tasks, and compute, rather than distillation.
Why It Matters
The model’s strong coding performance shows that large Chinese labs can match or exceed U.S. leaders with smaller models, potentially lowering barriers for deployment and accelerating cybersecurity research. It also highlights the importance of rapid release cycles and focused post‑training for frontier gains.
The Limitation
The article relies on the author’s interpretation of Z.ai’s blog and benchmark claims; independent third‑party evaluations are pending, and real‑world performance may vary.
What You Can Do
Benchmark GLM‑5.3 on your own coding tasks to see if its speed and accuracy meet your needs.
Source
Read original sourceWhy we picked this
GLM‑5.3 release from Chinese labs is a major new model announcement.