Gemini Live audio
What Changed
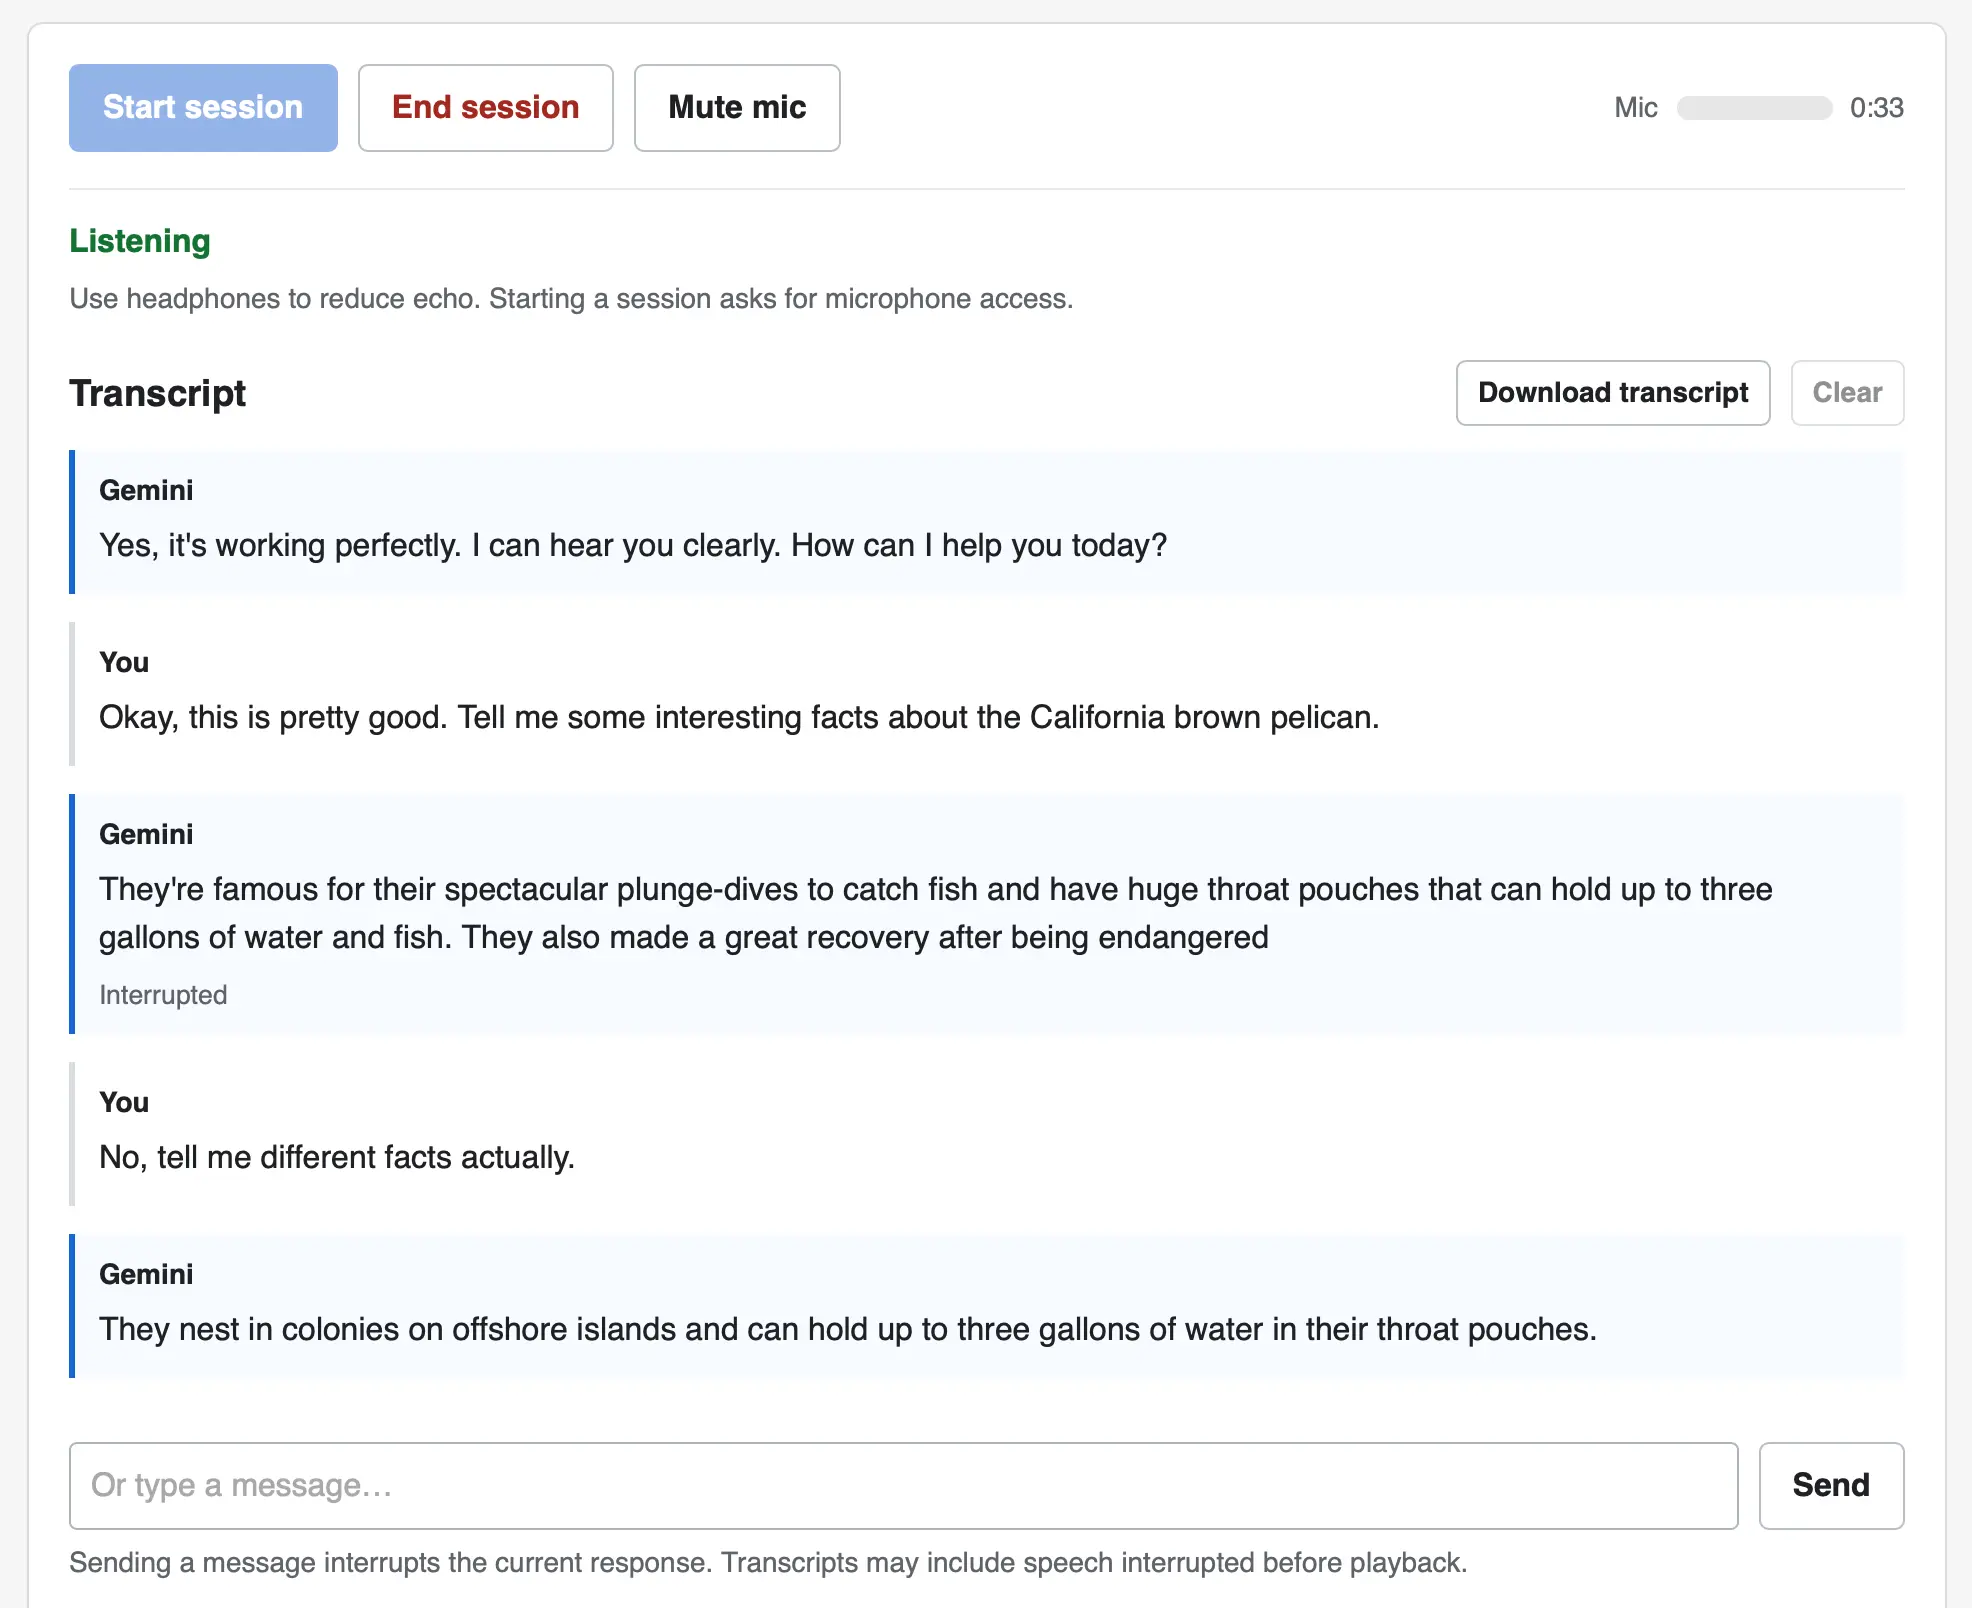
Google released Gemini 3.8 Live and 3.8 Live Extended Thinking, two speech‑to‑speech models similar to OpenAI’s GPT‑Live family. The author built a web UI that lets users select a model, voice preset, and optional system prompt, and start a voice conversation via a browser, with the ability to interrupt the model while it speaks. The implementation uses a WebSocket endpoint (wss://generativelanguage.googleapis.com/ws/google.ai.generativelanguage.v1alpha.GenerativeService.BidiGenerateContent) and the Web Audio API AudioContext for capture and playback, without external libraries.
Why It Matters
Enterprise architects can evaluate Gemini Live for real‑time voice interfaces, noting that it requires WebSocket connectivity and browser audio APIs, which may impact network and security policies. The ability to interrupt the model suggests more interactive user experiences but also introduces complexity in state management and latency considerations. Integration would need to address authentication, data privacy, and compliance with enterprise audio handling standards.
The Limitation
The example implementation relies on browser‑only APIs and no libraries, which may limit scalability and cross‑platform support in enterprise environments.
What You Can Do
Prototype a secure WebSocket gateway that proxies Gemini Live traffic and logs conversation metadata for audit purposes.